GPU Task Manager (gputaskman) has been released in version v0.4.5.
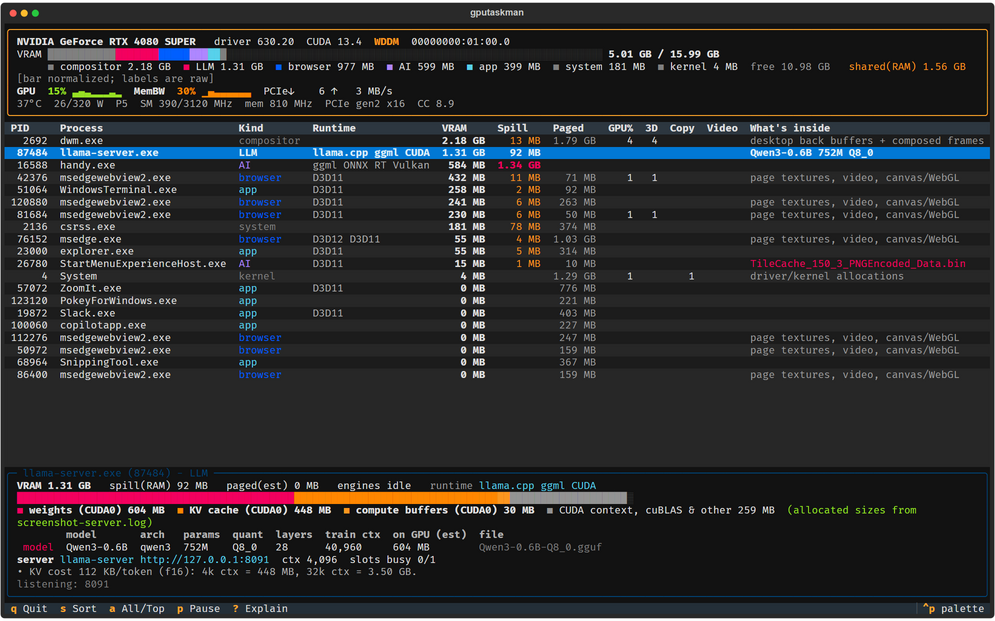
The experimental, open-source terminal tool is a sort of “htop for the GPU”: it shows per-process GPU memory and engine utilization. It runs on Linux, Windows, WSL and macOS.
After version 0.4.4, this is a bigger update with about 30 pull requests, mainly for more accurate readings and better error handling. New are, among other things, Intel Xe temperature reading, vLLM token rates and a --version option.
Changes in version 0.4.5:
- Preserve unknown WSL host counters instead of reporting zeros
- Mark failed macOS Metal client queries as unavailable
- Report NVML process-list failures instead of treating them as empty
- Invalidate WSL context ownership on immediate PID reuse
- Handle malformed runtime API responses
- Keep same-name GPU adapters in separate summary runs
- Label Intel GPU clock charts as GT
- Avoid private DRM attribution without client identity
- Avoid stale model logs as current allocations
- Restore container runtime API discovery without claiming ownership
- Hide Microsoft Basic Render Driver adapters
- Read Intel Xe package temperature from GPU hwmon labels
- Resolve llama-server’s relative model_path and –log-file against its cwd
- Cap GGUF header strings instead of reading whatever length the file claims
- Show compressed graphics peaks in summaries without adding them to VRAM
- Document TEXTUAL_THEME for choosing TUI colors
- Report vLLM prompt and generation token rates from /metrics
- Keep hidden NVML process VRAM out of measured totals
- Show the version: –version, TUI subtitle, upgrade notes in releases
Source: GitHub